Figure reports 56 percent success for humanoid in 30 unseen homes
The company rented the Bay Area properties for the test, and says an identical model trained without its human-video dataset managed 9 percent.
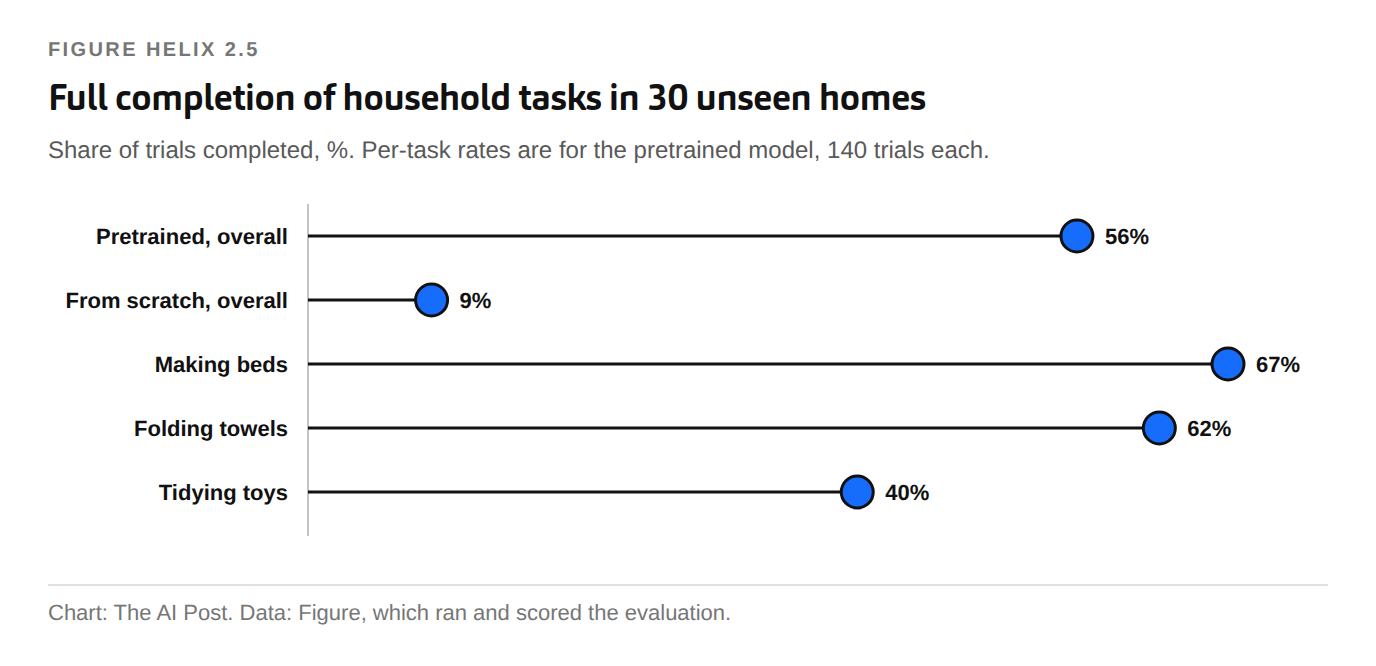
Figure released Helix 2.5 on Wednesday and said the model completed 56 percent of household tasks across 30 Bay Area homes it had not trained on. The company said it rented the properties for the evaluation. The robots tidied living rooms, folded towels and made beds.
The comparison Figure draws is with itself. An identical model trained without Index, its dataset of first-person human video, completed 9 percent of the same trials. The pretrained model finished 237 of 420 attempts, a gap the company puts at more than six times.
The breakdown is uneven. Figure gives bed-making as the strongest at 94 of 140 attempts, or 67 percent, with towel-folding at 87 of 140 and tidying toys into a basket at 56 of 140, around 40 percent. The company has not said why tidying lagged the other two.
The term zero-shot is narrower than it may appear. Figure says the robot had not seen the homes or the objects, but it specified the three tasks using fine-tuning data gathered elsewhere. The company gave no partial credit and counted every safety intervention as a failure.
The model sits on a large data and compute base. Figure says Index takes in roughly 35 minutes of recorded human activity every second, and that it has committed $3.5 billion in compute to training Helix. It also published four hours of unedited footage from the runs.
Tony Zhao of Sunday Robotics, quoted by Humanoids Daily, said the system is failing half the time, and that useful work needs reliability as well as generalisation. Figure ran the evaluation and scored it against its own rubric. No independent replication of the 56 percent figure has appeared.